The Adobe Acrobat Irony: Why the Unix Philosophy is the Real Antidote to Bloated Software
Looking at how Chrome accidentally built the world's favorite PDF viewer, the trap of the scalable multi-tenant illusion, and why the Unix philosophy of doing one thing well remains the best architectural principle for modern software and AI agent design.
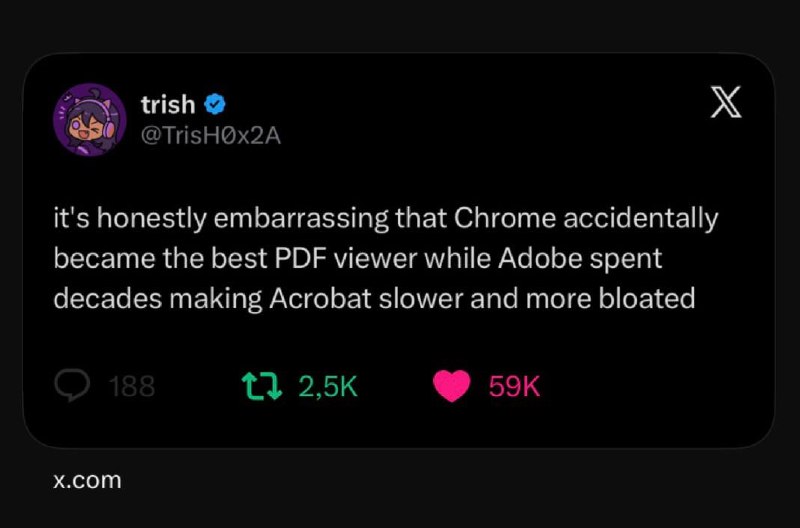
A few days ago, while scrolling through my X timeline, my attention was caught by a short, razor-sharp observation from @Trish0x2A:
"It's honestly embarrassing that Chrome accidentally became the best PDF viewer while Adobe spent decades making Acrobat slower and more bloated."

It hit close to home because this isn't just about Adobe. It points directly at a chronic illness plaguing modern commercial software: the curse of feature creep.
Consider the sheer irony: Adobe invented the PDF format in 1993. They wrote the standard, built the rendering engines, and owned the ecosystem from day one. Yet today, opening a two-page receipt or bank statement in Adobe Acrobat feels like initializing a spacecraft launch sequence.
Your laptop fans spin up. A splash screen holds you hostage. A dozen background services spring to life—Adobe Creative Cloud, Core Sync, IPC Broker, Genuine Service, crash reporters, auto-updaters. Before you even see the text, you are greeted with upsell prompts for cloud storage, e-signature workflows, and recently, an "AI Assistant" button demanding attention.
All you wanted was to read a document.
Then along came Google Chrome. The Chromium engineers originally just needed a lightweight component to render PDFs inside a browser tab so users didn't have to download files to their desktop first. No fuss: render the vector pages, scroll vertically, zoom in and out, print. Done.
The result? Chrome accidentally became the default PDF viewer for billions of people simply because it opens in 100 milliseconds and gets out of the way.
Why does good software almost inevitably decay into bloated, sluggish software?
Anatomy of the Disease: Why Software Gets Fat
The engineers who build bloated software aren't suffering from a skill issue. The problem isn't coding capability; it's misaligned systemic incentives.
-
The Quarterly "Value-Add" Trap
Tech companies live under constant pressure to demonstrate growth. Product teams must justify their existence during quarterly reviews. If an engineering team tells management, "This quarter we didn't add any new features; we made the core rendering engine 15% faster and cut idle RAM by half," it rarely earns promotions. But if you announce, "We just shipped cloud sync, digital signatures, and an integrated AI copilot into the PDF reader," executives applaud. New buttons look like progress. -
The Fear of Looking "Too Simple"
There is a pervasive cognitive bias that paid software must look complicated to justify its price tag. If an application presents a clean, quiet interface that simply does its job, enterprise procurement departments start asking: "Why are we paying thousands of dollars for something that looks this basic?" Complexity gets manufactured to defend enterprise pricing tiers. -
Conflating Core Functionality with Peripheral Plugins
Instead of keeping peripheral capabilities in isolated, optional modules, teams cram everything into the main runtime binary. Text editing, image compression, form validation, OCR, cloud backup, telemetry, and AI copilots all execute in the exact same process space.
The eventual outcome is always the same: a brittle monolithic monster that exhausts system resources and alienates its users.
The 1970s Remedy: The Unix Philosophy
Decades before the industry began debating microservices and containerization, Doug McIlroy and Ken Thompson at Bell Labs articulated architectural tenets that remain unmatched:
- Make each program do one thing well. To do a new job, build afresh rather than complicate old programs by adding new "features".
- Expect the output of every program to become the input to another, as yet unknown, program.
- Write programs to handle text streams, because that is a universal interface.
However, the Unix philosophy is frequently misunderstood.
Many developers assume it commands us to build trivial toy utilities with zero features, or they swing to the opposite destructive extreme: splintering every simple function into dozens of distributed microservices and separate OS processes. That mistake introduces massive network overhead, serialization costs, and debugging nightmares.
Building modular software does not require microservices, nor does it require dozens of independent background processes. Even within a single binary or monolithic codebase, true modularity is about strict interface boundaries, loose coupling, and absolute separation of concerns.
If an application's core responsibility is rendering documents, keep that rendering pipeline clean, focused, and unburdened. Never permit cloud synchronization, digital signing, or analytics routines to invade the critical execution path. If a capability is peripheral, encapsulate it as an optional plugin or an external tool.
The "Scalable Multi-Tenant" Illusion
This is the exact junction where engineers get blinded by enterprise buzzwords: the concept of multi-tenancy.
When most developers hear "scalable multi-tenant architecture," they instinctively visualize a colossal monolith hosting thousands of clients inside a single shared database. Every tenant is forced into identical tables, differentiated solely by a tenant_id column, and secured through layers of convoluted Row-Level Security (RLS) rules.
As traffic scales, the cracks appear immediately:
- Lock Contention: One tenant running an intensive analytical query drags down transaction throughput for every other tenant on the database.
- Catastrophic Blast Radius: A single corrupted table or uncaught deadlock takes down the entire application for every client simultaneously.
- Compliance & Privacy Nightmares: Enterprise security audits inevitably stall because sensitive financial or legal data physically shares disk blocks with unrelated teams.
The truth is simple: scalability and multi-tenancy do not require a single bloated monolith that swallows the entire company.
Under the Unix philosophy and the principles of Shared-Nothing architecture, the most resilient multi-tenant system is composed of independent instances.
If an enterprise has 20 teams, rather than introducing multi-tenant complexity into the application core, you simply spin up 20 isolated instances. One team equals one dedicated container.
- Data is physically separated at the storage tier (distinct files and volumes).
- Blast radius is virtually zero: if team A crashes their instance, team B experiences zero degradation.
- Resource allocation is enforced directly by kernel primitives (cgroups and container limits), rather than fallible application-level rate limiters.
When an organization inevitably requires centralized visibility across those 20 or 100 instances, the solution is not to bake multi-tenancy logic into the core engine. The correct solution is building a thin Fleet Control Plane / Orchestrator as an independent management layer above them.
This control plane handles provisioning, bulk configuration deployment, and centralized audit log collection. The application core itself stays clean, lightweight, and focused solely on its primary mission.
Enterprise Scale Through "Fleets", Not Fat Monoliths
This horizontal fleet pattern is not mere theory. The most battle-tested infrastructure software in the world relies on this exact model:
1. Docker Engine vs Kubernetes
Docker Engine never attempted to become a distributed cluster orchestrator inside its own daemon. Docker focuses strictly on being a container runtime on a single host: build images, execute containers, expose ports.
When organizations needed to coordinate across thousands of servers, the solution wasn't turning Docker Engine into an enormous distributed monolith. Instead, an entirely separate orchestration layer was built on top: Kubernetes. Docker remained focused and lightweight at the worker node level, while scheduling and cluster state were delegated to a dedicated orchestrator.
2. Prometheus vs Thanos / Cortex
Prometheus is intentionally designed as a single-node Time Series Database (TSDB). It contains no built-in clustering and no native distributed storage. That intentional constraint guarantees that metric collection continues running even when the rest of the network is in flames.
When enterprises require multi-year retention and unified querying across dozens of clusters, nobody rewrote Prometheus into an unwieldy distributed database. Prometheus instances stay single-node, and systems like Thanos or Cortex sit above them to federate queries across the fleet.
3. Grafana Agent vs Grafana Cloud
A local Grafana Agent focuses solely on scraping telemetry and forwarding streams to a designated backend. It does not render dashboards, process complex alerts, or manage user authentication. Responsibilities remain cleanly separated.
How We Apply This to Nouride
When designing Nouride—the multi-agent AI daemon powering our homelab and server workloads—the temptation to turn it into an "All-in-One Multi-Tenant Enterprise AI Platform" was everywhere.
We could easily have provisioned a PostgreSQL cluster, attached external vector databases like Qdrant or Milvus, implemented complex multi-tenant database schemas, and marketed it as "enterprise-ready."
But I rejected all of that in my head. We chose the Unix path:
- A Lean, Sovereign Engine:
Nouride runs as a single-binary sovereign daemon. Its primary datastore is an embedded SQLite instance (nouride.db), not an external database service. Its baseline memory footprint sits at ~107 MB RAM while coordinating 6 active agents across 10 concurrent gateway connections (Telegram, Discord, WhatsApp)—and in a minimal setup with 1–2 agents on a single active gateway, the baseline footprint drops to just around ~70 MB. - Pluggable Semantic Search:
Semantic retrieval via Ollama (bge-m3) is completely optional and pluggable, not a mandatory hard dependency baked into the core engine. If a user doesn't require semantic search or runs on hardware without a dedicated GPU, the engine operates on native SQLite FTS keyword search with zero memory penalty. - Multi-Tenancy via Fleets, Not Monoliths:
When enterprise teams require AI agents, we avoid embedding tenant isolation logic inside the Nouride binary. Our model: spin up one isolated Nouride container per team. The DevOps team operates an instance with terminal execution privileges (exec), while the Legal team operates a restricted instance with zero shell access. - Orchestration Stays Above:
Enterprise management across dozens of instances is handled by a separate project: the Fleet Control Plane. This upper management layer governs provisioning, configuration synchronization, and unified audit streaming, without compromising the simplicity of the core Nouride engine.
The Discipline of Saying "No" (Especially in Open Source)
Starting a software project is relatively easy. The real difficulty lies in preventing that software from decaying into unmaintainable bloat five years down the road.
Even though Nouride is not open source yet (perhaps down the road it will be), I firmly believe this principle applies universally—and this vulnerability is particularly acute across Open Source ecosystems.
Consider how many open source tools launch as lean, elegant, lightning-fast utilities that engineers love, only to degenerate into frustrating bloatware two years later.
The root cause is almost always the same: maintainers who cannot bring themselves to say "no".
Every proposed feature request is entertained. Every pull request submitted by users attempting to solve their hyper-specific edge case gets merged. Bit by bit, code volume swells, dependency trees tangle, attack surfaces expand, and the foundational clarity of the original project is completely lost.
Whenever a new feature or pull request arrives, the primary question for an engineer shouldn't be "Can we merge this?"
The real question must always be:
"Does adding this compromise the fundamental reason this software was created?"
Adobe Acrobat may have strayed too far into the thickets of corporate monetization and feature accumulation. But for the software we architect today—whether closed or open source—the choice remains ours: we can either follow the path toward sluggish bloat, or have the courage to refuse unnecessary complexity to keep our tools focused, sharp, and true to their purpose.